What Is Inferential Statistics? The Hidden Logic Behind Every Data Decision
When a pharmaceutical company announces that its new drug reduces symptoms by 30% based on trials with 500 participants, they’re not claiming the drug works for every patient—just that the evidence suggests it does for the broader population. That leap from sample to generalization isn’t guesswork; it’s the work of what is inferential statistics. This field bridges the gap between observed data and unobserved truths, allowing researchers, economists, and even marketers to draw conclusions from limited information. Without it, fields like medicine, finance, and social science would rely on anecdotes rather than evidence.
The power of inferential statistics lies in its ability to quantify uncertainty. Instead of treating data as absolute truths, it asks: How likely is this result if we repeated the study? Or: What’s the range of possible outcomes? These questions form the backbone of scientific rigor, from clinical trials to election polls. Yet for many, the term remains abstract—a black box where numbers magically translate into predictions. The reality is far more precise: it’s a systematic framework built on probability theory, sampling techniques, and mathematical models that turn noise into signal.
At its core, what is inferential statistics is about making educated guesses with measurable confidence. Whether you’re a data scientist interpreting survey results or a policymaker assessing economic trends, the principles remain the same: extract meaning from partial information while acknowledging the limits of what you can know. The stakes are high—misapplied inferential methods can lead to flawed policies, wasted resources, or even dangerous misdiagnoses. But when wielded correctly, it’s the difference between informed action and blind speculation.

The Complete Overview of What Is Inferential Statistics
Inferential statistics is the discipline that allows us to infer properties of a population from a sample. Unlike descriptive statistics—which summarizes data through means, medians, or standard deviations—it answers questions like: Is this pattern real, or did it happen by chance? This distinction is critical. For example, if a poll shows 52% of voters support a candidate, descriptive stats tell you the sample’s average. Inferential stats, however, estimate the true support level in the entire electorate, complete with a margin of error (e.g., ±3%). The latter is what drives decision-making in politics, advertising, and beyond.The field rests on three pillars: probability theory, sampling methods, and statistical inference techniques. Probability provides the mathematical foundation to quantify uncertainty (e.g., p-values, confidence intervals). Sampling ensures the data collected is representative enough to generalize. And inference techniques—such as regression, ANOVA, or chi-square tests—turn sampled data into predictions or hypotheses about larger groups. Together, these tools create a rigorous pipeline for turning data into actionable knowledge, even when full population data is impossible or impractical to collect.
Historical Background and Evolution
The origins of what is inferential statistics trace back to the 17th century, when mathematicians like Blaise Pascal and Pierre de Fermat laid the groundwork for probability theory. But it was the 18th and 19th centuries that saw its transformation into a scientific tool. Carl Friedrich Gauss’s work on the normal distribution (1809) and Pierre-Simon Laplace’s Analytical Theory of Probability (1812) formalized the idea of using samples to estimate population parameters. These advances were revolutionary: they allowed astronomers to predict planetary orbits and insurers to calculate risks based on incomplete data.The 20th century cemented inferential statistics as a cornerstone of modern science. Ronald Fisher’s contributions to experimental design and hypothesis testing (1920s–30s) standardized how researchers evaluate evidence. Meanwhile, Jerzy Neyman and Egon Pearson developed confidence intervals, shifting focus from proving hypotheses to quantifying uncertainty. The rise of computers in the late 20th century democratized these techniques, enabling industries to apply what is inferential statistics at scale—from quality control in manufacturing to algorithmic trading in finance. Today, it’s embedded in everything from A/B testing in tech to drug efficacy studies in healthcare.
Core Mechanisms: How It Works
At its heart, inferential statistics operates through sampling distributions and probability models. When you collect a sample (e.g., 1,000 survey responses), you assume it mirrors the population’s characteristics. But samples vary—one might overrepresent urban voters, another might skew older. Inferential methods account for this variability by calculating how much the sample’s statistics (like the mean) might differ from the population’s true values. For instance, a confidence interval of 95% around a sample mean (e.g., 52% ± 3%) means there’s a 95% chance the real population mean falls within that range.Table of Contents
- The Complete Overview of What Is Inferential Statistics
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does inferential statistics differ from descriptive statistics?
- Q: What’s the difference between a confidence interval and a margin of error?
- Q: Why can’t we just use the entire population instead of a sample?
- Q: What does a p-value of 0.05 actually mean?
- Q: How do Bayesian and frequentist approaches to inferential statistics differ?
- Q: Can inferential statistics be misused? If so, how?
- Q: What fields rely most heavily on inferential statistics?
The process hinges on two key concepts: estimators and tests. An estimator (e.g., the sample mean) approximates a population parameter (e.g., the true mean). Tests like t-tests or z-tests compare observed data to a null hypothesis (e.g., "the drug has no effect") to determine statistical significance. The p-value, often misunderstood, quantifies the probability of observing the data if the null hypothesis were true—a low p-value (typically <0.05) suggests the hypothesis should be rejected. Critically, inferential statistics doesn’t "prove" anything; it provides probabilistic support for conclusions, forcing users to acknowledge trade-offs between precision and confidence.
Key Benefits and Crucial Impact
The value of what is inferential statistics lies in its ability to replace uncertainty with measurable risk. In business, it transforms marketing strategies—companies use inferential models to predict customer behavior from partial data, reducing costly trial-and-error. In healthcare, it underpins clinical trials, ensuring new treatments meet rigorous standards before approval. Even social sciences rely on it to draw causal inferences from observational studies, where experiments aren’t feasible. Without these tools, decisions would be based on intuition, not evidence—a recipe for inefficiency or failure.The discipline’s impact extends to risk management. Banks use inferential models to assess loan defaults; insurers price policies based on actuarial estimates derived from sampled claims. Governments deploy it to forecast economic trends or election outcomes. The common thread? All these applications require extrapolating from limited data to broader contexts—something only inferential statistics can provide with transparency.
"Inferential statistics is the art of learning from data what you can’t see." — David Freedman, Statistician and Economist
Major Advantages
- Generalization: Enables conclusions about entire populations (e.g., voters, patients) from small, representative samples, saving time and resources.
- Uncertainty Quantification: Provides confidence intervals and p-values to communicate the reliability of findings, avoiding overconfidence in noisy data.
- Hypothesis Testing: Structured frameworks (e.g., null hypothesis testing) to evaluate claims objectively, reducing bias in decision-making.
- Predictive Power: Models like regression or time-series analysis forecast future trends (e.g., sales, disease outbreaks) based on historical patterns.
- Adaptability: Techniques scale from simple A/B tests in tech to complex Bayesian networks in AI, accommodating diverse research needs.

Comparative Analysis
| Inferential Statistics | Descriptive Statistics |
|---|---|
| Focuses on making predictions or inferences about a population from sample data. | Summarizes and describes data through measures like mean, median, or standard deviation. |
| Uses probability theory to estimate population parameters (e.g., confidence intervals). | Provides no information about broader populations—only the observed dataset. |
| Key tools: Hypothesis tests (t-tests, chi-square), regression analysis, Bayesian methods. | Key tools: Histograms, box plots, correlation coefficients. |
| Example: Determining if a new drug’s success in trials (sample) applies to all patients (population). | Example: Calculating the average income of a surveyed group. |
Future Trends and Innovations
The integration of what is inferential statistics with machine learning is reshaping its future. Traditional methods like p-values are being supplemented (or challenged) by Bayesian approaches, which update probabilities as new data arrives—ideal for real-time applications like fraud detection or dynamic pricing. Meanwhile, advances in computational power are enabling causal inference, a subset that identifies not just correlations but direct cause-and-effect relationships, critical for policy and medicine.Another frontier is explainable AI (XAI), where inferential techniques help demystify black-box models. As algorithms grow more complex, methods like SHAP values or counterfactual analysis rely on statistical inference to interpret their decisions. The challenge ahead? Balancing statistical rigor with the speed demands of big data. Innovations in scalable Bayesian methods and non-parametric statistics may bridge this gap, ensuring inferential stats remain relevant in an era of petabyte datasets and automated decision-making.
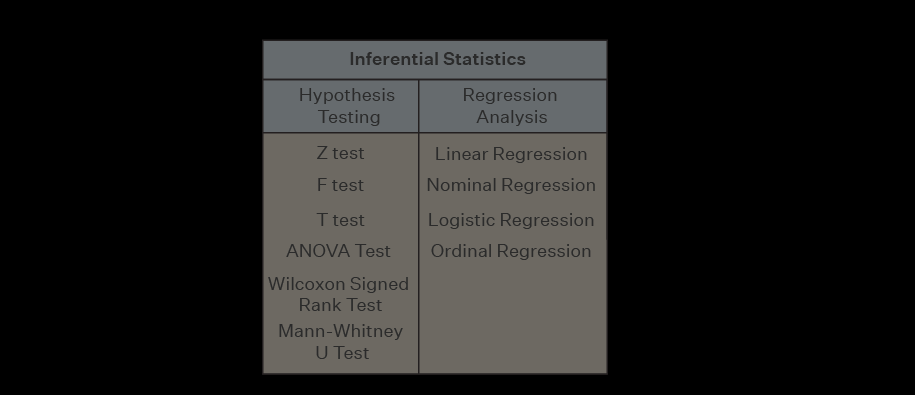
Conclusion
What is inferential statistics is more than a tool—it’s the scaffold that supports evidence-based decision-making across disciplines. Its principles ensure that when we say "this drug works" or "this policy will succeed," we’re not just asserting confidence; we’re quantifying it. The discipline’s evolution reflects humanity’s quest to turn chaos into clarity, from 18th-century gamblers to 21st-century data scientists. Yet its core remains unchanged: to draw meaningful conclusions from imperfect information.As data grows in volume and complexity, the need for robust inferential methods will only intensify. Whether you’re a researcher designing experiments or a business leader interpreting trends, understanding these concepts isn’t optional—it’s the difference between acting on noise and acting on insight. The future belongs to those who wield inferential statistics not as a black box, but as a precise language for navigating uncertainty.
Comprehensive FAQs
Q: How does inferential statistics differ from descriptive statistics?
A: Descriptive statistics summarize data (e.g., "the average test score is 75"), while inferential statistics uses data to make predictions or inferences about a larger population (e.g., "we’re 95% confident the true average is between 72 and 78"). The former answers what is; the latter answers what might be.
Q: What’s the difference between a confidence interval and a margin of error?
A: A confidence interval (e.g., 52% ± 3%) is a range (49% to 55%) estimated to contain the true population parameter with a certain probability (e.g., 95%). The margin of error (3%) is half the width of that interval. Both are tools of inferential statistics to express uncertainty.
Q: Why can’t we just use the entire population instead of a sample?
A: Sampling is often necessary due to cost, time, or feasibility. For example, testing every voter’s opinion before an election is impossible. Inferential statistics allows us to estimate population characteristics from a representative subset, with quantifiable error margins.
Q: What does a p-value of 0.05 actually mean?
A: A p-value of 0.05 means there’s a 5% probability of observing the data (or something more extreme) if the null hypothesis were true. It doesn’t prove the null is false—only that the evidence is strong enough to reject it, assuming the test was properly designed.
Q: How do Bayesian and frequentist approaches to inferential statistics differ?
A: Frequentist methods (e.g., p-values) treat probabilities as long-run frequencies (e.g., "this result would occur 5% of the time under the null"). Bayesian methods incorporate prior beliefs, updating probabilities as new data arrives. The choice depends on the context: Bayesian is flexible for iterative learning; frequentist is rigorous for hypothesis testing.
Q: Can inferential statistics be misused? If so, how?
A: Yes. Common pitfalls include p-hacking (cherry-picking data to achieve significance), ignoring effect sizes (focusing only on p-values), or using non-representative samples. Misuse often stems from conflating statistical significance with practical importance or overlooking assumptions (e.g., normality, independence). Always scrutinize methodology.
Q: What fields rely most heavily on inferential statistics?
A: Fields where full population data is unobtainable or where causal conclusions are critical:
- Healthcare (clinical trials, epidemiology)
- Social sciences (survey research, economics)
- Business (market research, A/B testing)
- Engineering (quality control, reliability testing)
- Political science (polling, policy evaluation)
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Viralcontentbee.