How HashMap in Java Powers Modern Data Structures
At its core, the hashmap java implementation is a cornerstone of Java’s Collections Framework, offering O(1) average-time complexity for critical operations like insertion, deletion, and lookup. Unlike traditional arrays or linked lists, where traversal scales linearly with data size, a well-designed hashmap java structure distributes elements across memory using hashing, reducing collisions and ensuring predictable performance. This makes it indispensable for caching systems, database indexing, and real-time analytics where speed is non-negotiable.
The elegance of hashmap java lies in its balance between simplicity and efficiency. While other languages like Python or C++ offer similar constructs (e.g., dictionaries or unordered_maps), Java’s hashmap java distinguishes itself through thread-unsafe optimizations, customizable hash functions, and seamless integration with generics. Developers leveraging it for high-frequency trading, recommendation engines, or large-scale log processing often cite its reliability as a deciding factor—yet its nuances, from resizing strategies to load factor tuning, remain underappreciated.
What sets Java’s hashmap java apart is its adaptability. Whether you’re modeling a sparse matrix, implementing a LRU cache, or optimizing a multi-threaded web server, the structure’s flexibility allows for fine-grained control over memory usage and collision resolution. But beneath its surface, the mechanics—hashing algorithms, bucket chaining, and dynamic resizing—demand precision. Misconfigured load factors or weak hash functions can degrade performance from O(1) to O(n), turning a strength into a bottleneck.

The Complete Overview of HashMap in Java
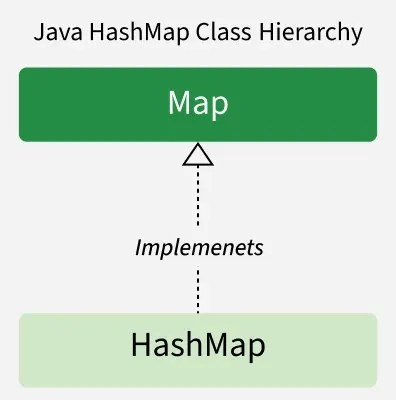
The hashmap java class, introduced in Java 1.2 as part of the Collections Framework, represents a hash table-based implementation of the `Map` interface. Unlike its predecessor `Hashtable` (which was synchronized by default), hashmap java prioritizes performance by trading thread safety for speed, making it the default choice for single-threaded applications. Its design centers on three pillars: hashing, collision resolution, and dynamic resizing, each engineered to minimize latency in key-value operations.Under the hood, hashmap java relies on an array of "buckets" (initially 16 in size) where each bucket holds a linked list (or, post-Java 8, a balanced tree) of entries. When a key is inserted, its hash code is computed, combined with a salt (to mitigate hash collisions from malicious inputs), and mapped to a bucket index via modulo arithmetic. This process ensures that even with millions of entries, the average lookup time remains constant—provided the load factor (default 0.75) is respected.
Historical Background and Evolution
The concept of hash tables dates back to the 1950s, but Java’s hashmap java as we know it emerged from the need for a high-performance, type-safe alternative to `Hashtable`. Before Java 8, hashmap java used separate chaining (linked lists) exclusively to handle collisions, which could degrade to O(n) in worst-case scenarios (e.g., all keys hashing to the same bucket). The 2014 release of Java 8 introduced a pivotal optimization: treeification, where linked lists longer than eight nodes were converted into red-black trees, guaranteeing O(log n) performance for skewed distributions.This evolution reflects broader trends in Java’s optimization philosophy—balancing theoretical guarantees with practical trade-offs. For instance, the decision to make hashmap java non-synchronized (unlike `Hashtable`) was controversial but justified by the rise of concurrent collections like `ConcurrentHashMap`. Meanwhile, the introduction of `HashMap.compute()` and `merge()` methods in Java 8 further cemented its role as a versatile tool for functional-style operations, aligning with modern paradigms of immutable data processing.
Core Mechanisms: How It Works
At its simplest, hashmap java’s operation flow is:1. Hashing: The `hash()` method computes a hash code for the key, then applies a bitwise operation (`key.hashCode() ^ (key.hashCode() >>> 16)`) to distribute values more uniformly.
2. Indexing: The hash code is masked against the current capacity (e.g., `15 & hash`) to determine the bucket index.
3. Collision Handling: If multiple keys map to the same bucket, entries are stored in a linked list (or tree, post-Java 8). The `equals()` method resolves key comparisons during lookups.
Table of Contents
- The Complete Overview of HashMap in Java
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does HashMap use 0.75 as the default load factor?
- Q: How does Java 8’s treeification improve HashMap performance?
- Q: Can I use HashMap with null keys or values?
- Q: What happens during a HashMap resize operation?
- Q: How do I choose between HashMap and LinkedHashMap?
- Q: Why might my HashMap degrade to O(n) performance?
The dynamic resizing mechanism kicks in when the number of entries exceeds `capacity loadFactor`. The map doubles its capacity (e.g., from 16 to 32), rehashes all keys, and redistributes them across the new buckets. This amortized O(1) resizing ensures that frequent insertions don’t trigger costly operations mid-execution.
Key Benefits and Crucial Impact
Few data structures offer the hashmap java’s blend of simplicity and power. Its O(1) average-case operations make it ideal for scenarios where latency is critical—whether indexing a document corpus, implementing a session store in a web app, or accelerating scientific simulations. The structure’s memory efficiency (storing only key-value pairs without metadata overhead) further reduces footprint compared to alternatives like `TreeMap`.Beyond raw performance, hashmap java’s integration with Java’s generics system enables type-safe operations, eliminating runtime `ClassCastException`s. This safety net, combined with its thread-local optimizations, has made it the default choice for developers building high-throughput systems. As Josh Bloch noted in Effective Java, "HashMap is to Map as ArrayList is to List—preferred in most cases unless you need ordering or synchronization."
"The beauty of HashMap lies in its ability to turn a problem that would otherwise require O(n) time into one that runs in constant time—with minimal overhead." — Joshua Bloch, Effective Java
Major Advantages
- Constant-Time Operations: Average-case O(1) for `get()`, `put()`, and `remove()`, making it ideal for real-time systems.
- Memory Efficiency: Stores only key-value pairs without additional metadata (unlike `TreeMap`, which maintains a sorted order).
- Flexible Key Types: Supports any `Object` as a key, provided it implements `hashCode()` and `equals()` correctly.
- Dynamic Resizing: Automatically adjusts capacity to maintain performance as data grows, reducing manual tuning.
- Java 8+ Optimizations: Treeification for collision-heavy buckets and functional-style methods (`computeIfAbsent()`, `merge()`) enhance usability.
Comparative Analysis
| Feature | HashMap (Java) | TreeMap (Java) | ConcurrentHashMap (Java) |
|---|---|---|---|
| Ordering | Unordered (insertion order, post-Java 7) | Sorted (natural order or Comparator) | Unordered |
| Thread Safety | Not thread-safe (fail-fast) | Not thread-safe | Thread-safe (segmented locking) |
| Performance (Avg. Case) | O(1) for get/put | O(log n) for all operations | O(1) for get/put (concurrent) |
| Use Case | High-speed key-value storage | Ordered data or range queries | Multi-threaded environments |
Future Trends and Innovations
The hashmap java’s trajectory is shaped by two competing demands: scalability and predictability. As applications migrate to distributed systems, hybrid approaches like consistent hashing (used in databases like DynamoDB) may influence Java’s future implementations, though backward compatibility remains a hurdle. Meanwhile, advancements in GPU-accelerated hashing could redefine collision resolution, leveraging parallel processing to handle skewed distributions.Another frontier is immutable maps, where structures like `java.util.ImmutableMap` (from libraries like Guava) offer thread-safe alternatives to `ConcurrentHashMap` for read-heavy workloads. These trends hint at a broader shift: hashmap java will continue evolving not just in performance, but in how it integrates with modern architectures—whether through reactive programming models or quantum-resistant hashing algorithms.

Conclusion
Java’s hashmap java is more than a data structure; it’s a testament to the language’s ability to balance theory and practice. Its design—rooted in hashing, collision avoidance, and dynamic scaling—has made it the workhorse of countless applications, from embedded systems to cloud-native services. Yet, its power is only as strong as the developer’s understanding of its internals: load factors, hash functions, and resizing strategies.As Java evolves, so too will hashmap java, adapting to new challenges like distributed computing and real-time analytics. For now, mastering its mechanics remains essential—whether you’re optimizing a trading algorithm or building a scalable microservice. The key lies not just in using hashmap java, but in using it intelligently.
Comprehensive FAQs
Q: Why does HashMap use 0.75 as the default load factor?
The load factor of 0.75 is a trade-off between memory usage and performance. At this threshold, the map resizes before collisions become frequent, maintaining O(1) average-time complexity. A lower factor (e.g., 0.5) reduces collisions but wastes memory; a higher factor (e.g., 0.9) risks performance degradation.
Q: How does Java 8’s treeification improve HashMap performance?
Treeification converts linked lists into balanced trees when they exceed eight nodes, ensuring O(log n) lookups instead of O(n). This prevents worst-case scenarios where all keys collide into a single bucket, which would otherwise degrade performance to linear time.
Q: Can I use HashMap with null keys or values?
Yes, but with restrictions: HashMap allows exactly one `null` key and multiple `null` values. Attempting to insert a second `null` key throws a `NullPointerException`. This design choice simplifies collision handling for `null` (always mapped to bucket 0).
Q: What happens during a HashMap resize operation?
When the map exceeds its capacity × load factor, it:
1. Creates a new array with double the capacity.
2. Rehashes all existing entries into the new array.
3. Updates the capacity and threshold.
This is an expensive O(n) operation, so resizing is amortized over many insertions to maintain O(1) average time.
Q: How do I choose between HashMap and LinkedHashMap?
Use HashMap for pure performance (unordered, fastest lookups). Use LinkedHashMap if you need:
Q: Why might my HashMap degrade to O(n) performance?
Performance degrades to O(n) in two cases:
1. Poor Hashing: Weak `hashCode()` implementations (e.g., always returning the same value) cause all keys to collide.
2. Skewed Distribution: Many keys hash to the same bucket, especially if the initial capacity is too small or the load factor is too high.
Monitoring collision rates via tools like VisualVM can help diagnose these issues.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Viralcontentbee.