What Is a T-Test? The Statistical Tool Shaping Modern Research
When researchers compare two groups—whether it’s testing a new drug’s efficacy against a placebo or evaluating student performance before and after a teaching intervention—they rely on a statistical method so fundamental it has become a cornerstone of empirical inquiry. This method, known as the t-test, is the workhorse of inferential statistics, offering a precise way to determine whether observed differences between groups are statistically significant or merely due to random variation. Its elegance lies in its simplicity: a single numerical output (the t-value) distills complex probability into a clear yes-or-no answer about whether an effect exists. Yet beneath this simplicity is a rigorous mathematical framework that has evolved over a century, adapting to everything from clinical trials to machine learning.
The ubiquity of what is a t-test questions in academic journals, policy reports, and even courtroom evidence underscores its indispensable role. It’s not just a tool for statisticians—it’s a language for scientists, economists, and social researchers to communicate certainty (or uncertainty) about their findings. But mastery of the t-test requires more than memorizing formulas; it demands an understanding of its assumptions, limitations, and the subtle ways it can mislead when misapplied. From its origins in early 20th-century biometry to its current use in high-dimensional datasets, the t-test remains a testament to how statistical theory can bridge raw data and actionable insight.
At its core, the t-test addresses a deceptively simple question: Is the difference between two means meaningful, or could it have arisen by chance? The answer hinges on three pillars: sample size, variance within groups, and the magnitude of the observed difference. These elements interact in a way that reveals whether the data supports a hypothesis—or exposes it as an artifact of sampling error. For researchers, this distinction is everything.
The Complete Overview of What Is a T-Test
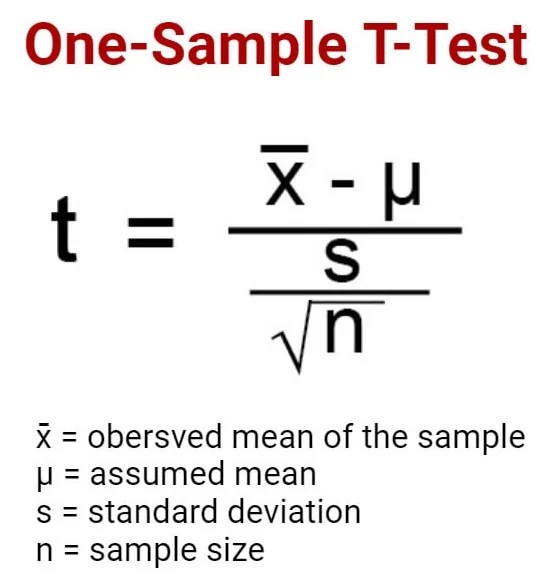
The t-test is a parametric statistical procedure designed to evaluate differences between two population means by analyzing sample data. Unlike descriptive statistics, which summarize data (e.g., mean, standard deviation), the t-test provides a what is a t-test framework to make inferences about whether those differences are statistically significant—that is, unlikely to occur if the null hypothesis (typically, "no difference exists") were true. Its versatility stems from three primary variants: the independent samples t-test (comparing two distinct groups), the paired t-test (comparing the same subjects before/after treatment), and the one-sample t-test (comparing a single group to a known population mean). Each variant adjusts for different experimental designs, but all share the same underlying principle: calculating a test statistic (t) that balances the observed difference against the variability in the data.What makes the t-test particularly powerful is its reliance on the t-distribution, a probability distribution that accounts for small sample sizes where the normal distribution’s assumptions break down. This adaptation was revolutionary in the early 1900s, when datasets were often limited to dozens of observations. Today, while larger samples may justify approximations like the z-test, the t-test’s robustness and intuitive output (the p-value) ensure its dominance in fields where precision matters—from pharmaceutical trials to A/B testing in tech. Its ability to quantify uncertainty in a single metric (t = (mean difference) / (standard error)) has cemented its place as the first tool researchers reach for when asking, "Is this effect real?"
Historical Background and Evolution
The t-test’s origins trace back to 1908, when William Sealy Gosset—writing under the pseudonym "Student" to conceal his employer’s (Guinness Brewery’s) secrecy—published "The Probable Error of a Mean" in Biometrika. Gosset’s breakthrough was solving a problem that plagued early statisticians: how to estimate population parameters from small samples where the normal distribution’s reliance on known standard deviations was impractical. His solution, the t-distribution, introduced degrees of freedom—a concept that would later become central to modern statistical theory. The t-test, as we know it, emerged as a direct application of this distribution, offering a way to compare means without assuming knowledge of the population variance.The method’s adoption was swift, particularly in biology and agriculture, where controlled experiments were rare and sample sizes modest. By the 1920s, Ronald Fisher and others expanded its use, formalizing the null hypothesis significance testing (NHST) framework that underpins the t-test today. Fisher’s contributions—including the F-test for comparing multiple means—built on Gosset’s work, but the t-test retained its simplicity and accessibility. In the digital age, its evolution has been less about theoretical refinements and more about computational scalability: modern software (R, Python, SPSS) automates t-tests for datasets with millions of observations, while machine learning has revived debates about its assumptions in high-dimensional spaces. Yet, at its heart, the t-test remains Gosset’s legacy—a tool that democratized statistical rigor for researchers without advanced mathematical training.
Core Mechanisms: How It Works
The mechanics of what is a t-test revolve around a single equation:t = (X̄₁ − X̄₂) / (sₚ √(1/n₁ + 1/n₂)) Here, X̄₁ and X̄₂ are the sample means, sₚ is the pooled standard deviation (a weighted average of group variances), and n₁, n₂ are sample sizes. This formula computes the t-statistic, which is then compared to critical values from the t-distribution (or converted to a p-value) to assess significance. The key insight is that the denominator—standard error—captures the uncertainty in the mean difference due to sampling variability. A large t-value (absolute) suggests the observed difference is unlikely under the null hypothesis, while a small t-value implies the data is consistent with no effect.
Table of Contents
- The Complete Overview of What Is a T-Test
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What is the difference between a t-test and a z-test?
- Q: Can a t-test be used for non-normal data?
- Q: How do I know if my data meets the homogeneity of variance assumption?
- Q: What does a high t-value mean?
- Q: Why should I report effect size alongside a t-test?
- Q: What are common mistakes when using a t-test?
The t-test’s assumptions are critical to its validity. It assumes:
1. Normality: Data in each group should be approximately normally distributed (robust with larger samples).
2. Homogeneity of variance: Group variances should be equal (checked via Levene’s test).
3. Independence: Observations within and between groups must be independent.
Violations of these assumptions can lead to inflated Type I or II errors, necessitating alternatives like the Mann-Whitney U test (non-parametric) or Welch’s t-test (unequal variances). Understanding these mechanics is why researchers often pre-process data (e.g., transformations, outlier removal) before applying what is a t-test—to ensure the method’s integrity.
Key Benefits and Crucial Impact
The t-test’s impact on research is immeasurable. It transforms raw data into actionable insights, allowing scientists to claim causality with statistical confidence. In medicine, for example, a t-test might confirm whether a new treatment reduces blood pressure more than a placebo, justifying further investment. In education, it could reveal whether a teaching method improves test scores beyond chance. Even in business, A/B tests—often analyzed with t-tests—drive decisions on product features, ad campaigns, or pricing strategies. Its role in peer-reviewed journals is equally pivotal: editors and reviewers demand rigorous hypothesis testing, and the t-test provides the gold standard for comparing two groups.The method’s elegance lies in its balance of simplicity and precision. A single p-value (e.g., p < 0.05) communicates complex uncertainty in a universally understood metric. This clarity has made the t-test the default choice for introductory statistics courses, ensuring generations of researchers inherit its principles. Yet, its power comes with responsibility: misapplication—such as ignoring non-normality or multiple comparisons—can lead to false conclusions with far-reaching consequences. As one statistician noted:
"The t-test is like a scalpel: it can perform life-saving surgery, but in the wrong hands, it can cause irreparable harm. Its strength is its precision; its weakness is its fragility when assumptions are violated." — George Box, Statistician and Economist
Major Advantages
The t-test’s dominance stems from five key advantages:
Comparative Analysis
While the t-test is versatile, other methods serve specific needs. Below is a comparison of key statistical tests:| Test Type | Use Case |
|---|---|
| T-Test | Comparing means of two groups (normal data, equal variances). |
| ANOVA | Comparing means across three+ groups (extension of t-test). |
| Mann-Whitney U | Non-parametric alternative for ordinal data or unequal variances. |
| Z-Test | Comparing means with known population variance (large samples). |
Future Trends and Innovations
As data grows larger and more complex, the t-test faces new challenges—and opportunities. In big data contexts, traditional t-tests may fail due to non-normality or multicollinearity, prompting researchers to explore permutation tests or Bayesian alternatives that don’t rely on distributional assumptions. Machine learning has also revived interest in effect size over p-values, as models like random forests or neural networks can identify interactions the t-test overlooks. Yet, the t-test’s core principle—quantifying uncertainty in group differences—remains relevant. Future innovations may lie in hybrid approaches, such as combining t-tests with resampling methods (bootstrapping) to handle small samples or high-dimensional data.One emerging trend is the replication crisis, which has exposed flaws in over-reliance on p-values. This has led to calls for reporting confidence intervals, effect sizes, and Bayesian credible intervals alongside t-test results—a shift that could redefine how what is a t-test is interpreted in research. As statistics evolves, the t-test’s role may shrink in some domains but endure as a foundational tool for teaching and exploratory analysis. Its legacy is not just in its equations but in the critical thinking it fosters about data and uncertainty.

Conclusion
The t-test is more than a statistical formula—it’s a lens through which researchers examine the world. From Gosset’s brewery lab to modern clinical trials, its ability to distill complex data into a single question ("Is this difference meaningful?") has made it indispensable. Yet, its power is matched by its limitations: assumptions must be met, effect sizes must be considered, and context must guide interpretation. The t-test’s future may involve integration with advanced methods, but its principles will endure as long as researchers seek clarity in uncertainty.For practitioners, the takeaway is clear: what is a t-test is not just about running a function in software—it’s about understanding when to use it, how to validate its assumptions, and how to communicate its results responsibly. In an era of data deluge, the t-test remains a reminder that rigor matters more than volume.
Comprehensive FAQs
Q: What is the difference between a t-test and a z-test?
A: The t-test uses the t-distribution to estimate variance from sample data (ideal for small samples), while the z-test assumes known population variance (used with large samples where the normal distribution suffices). The t-test is more robust for real-world scenarios where variance is unknown.
Q: Can a t-test be used for non-normal data?
A: The t-test assumes normality, but it’s relatively robust for moderate violations, especially with larger sample sizes (n > 30). For severely non-normal data, use non-parametric alternatives like the Mann-Whitney U test or apply transformations (e.g., log, square root) to meet assumptions.
Q: How do I know if my data meets the homogeneity of variance assumption?
A: Use Levene’s test or Bartlett’s test to check for equal variances. If p > 0.05, variances are likely equal. If not, consider Welch’s t-test (unequal variances) or transform your data (e.g., log transformation for skewed data).
Q: What does a high t-value mean?
A: A high absolute t-value (e.g., |t| > 2) indicates a large difference between group means relative to the variability in the data, suggesting the null hypothesis (no difference) is unlikely. However, significance depends on degrees of freedom and the chosen alpha level (e.g., 0.05).
Q: Why should I report effect size alongside a t-test?
A: The p-value alone doesn’t indicate practical significance. Effect sizes (e.g., Cohen’s d, η²) quantify the magnitude of the difference, helping researchers assess whether the result is meaningful beyond statistical significance. For example, a p < 0.05 with d = 0.1 suggests a trivial effect, while d = 0.8 indicates a strong one.
Q: What are common mistakes when using a t-test?
A: Common pitfalls include:
1. Ignoring assumptions (non-normality, unequal variances).
2. Running multiple t-tests without correcting for multiple comparisons (inflates Type I error).
3. Using paired t-tests on independent samples (or vice versa).
4. Interpreting p-values as evidence of causality (correlation ≠ causation).
5. Overlooking outliers or influential points that skew results.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Viralcontentbee.