Why Developers Love (or Hate) SQL Server ILIKE It Not – The Hidden Power of Case-Insensitive Queries
SQL Server’s `LIKE` operator is a staple of database querying, but when case sensitivity becomes an obstacle, developers often turn to alternatives. The phrase "sql server ilike it not" isn’t just a quirky typo—it reflects a deeper struggle with case-insensitive pattern matching in T-SQL. Unlike PostgreSQL’s native `ILIKE`, SQL Server lacks a direct equivalent, forcing practitioners to improvise with `COLLATE`, `UPPER()`, or `LOWER()` functions. The frustration stems from a simple truth: what seems like a minor syntax tweak can drastically alter query behavior, especially in multicultural or legacy systems where case conventions vary wildly.
The confusion deepens when developers attempt to negate the `ILIKE`-like behavior—"sql server ilike it not"—only to realize SQL Server doesn’t natively support `NOT ILIKE`. This omission isn’t just a documentation gap; it’s a design choice that ripples through application logic, forcing workarounds that can degrade performance or introduce bugs. For example, a query like `WHERE column NOT LIKE 'pattern'` might return unintended results if the collation treats `'Pattern'` and `'pattern'` differently. The lack of a standardized `ILIKE` in SQL Server turns what should be a straightforward operation into a puzzle, where every solution trades off between readability and efficiency.
At its core, the issue boils down to SQL Server’s adherence to Windows collation settings, which can be both a blessing and a curse. While this allows fine-grained control over sorting and comparison rules, it also means developers must account for collation dependencies—something often overlooked in haste. The phrase "sql server ilike it not" thus becomes a shorthand for a broader challenge: reconciling SQL Server’s idiosyncrasies with the expectations of modern, case-agnostic applications.
The Complete Overview of SQL Server’s Case-Insensitive Querying
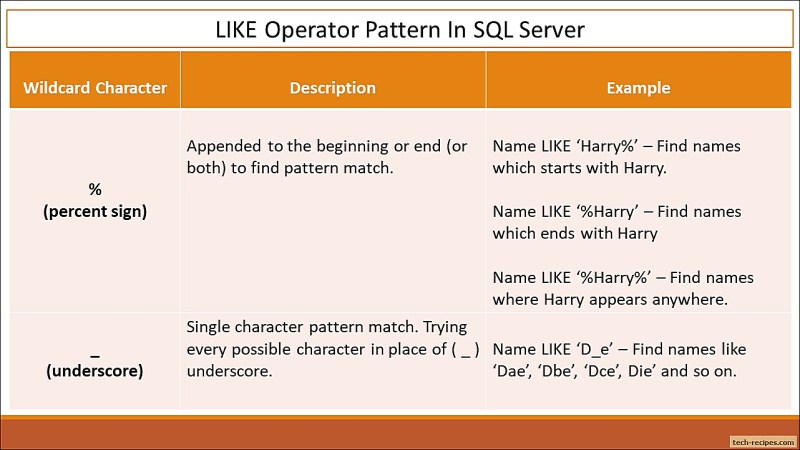
SQL Server’s handling of case-insensitive searches is a study in compromise. While the `LIKE` operator itself is case-sensitive by default (unless a case-insensitive collation is applied), developers frequently need to simulate `ILIKE`-like behavior—hence the informal "sql server ilike it not" shorthand. The absence of a native `ILIKE` function means practitioners must rely on collation clauses (`COLLATE`) or explicit case conversion (`UPPER()`/`LOWER()`), each with trade-offs. For instance, `COLLATE SQL_Latin1_General_CP1_CI_AS` enforces case insensitivity at the collation level, but this approach can impact index usage and performance, especially in large datasets.The need for case-insensitive matching isn’t just academic; it’s a practical necessity in global applications where user input varies in case conventions. A query like `SELECT FROM Users WHERE Username LIKE 'john'` might miss `'JOHN'` or `'JoHn'` unless explicitly handled. This is where "sql server ilike it not" becomes a mantra for developers—acknowledging that SQL Server’s default behavior often doesn’t align with real-world use cases. The workaround ecosystem around this limitation has given rise to patterns like:
```sql
WHERE UPPER(column) LIKE '%PATTERN%'
```
or
```sql
WHERE column COLLATE SQL_Latin1_General_CP1_CI_AS LIKE 'pattern'
```
Both approaches achieve the same goal but with different implications for query plans and maintainability.
Historical Background and Evolution
The roots of SQL Server’s case-sensitivity quirks trace back to its early days as a Windows-centric database. Microsoft’s decision to tie collation to Windows’ locale settings (e.g., `SQL_Latin1_General_CP1_CI_AS`) was pragmatic—it allowed databases to mirror the case-folding rules of the underlying OS. However, this design choice created a divide with other RDBMS like PostgreSQL, which introduced `ILIKE` in 2001 as a direct response to the need for consistent case-insensitive pattern matching. SQL Server’s lack of a native `ILIKE` wasn’t an oversight; it was a deliberate alignment with its collation-first philosophy.Over time, this approach has led to fragmented best practices. Developers in SQL Server-heavy environments often resort to dynamic SQL or stored procedures to abstract away collation dependencies, while PostgreSQL users benefit from a cleaner syntax. The phrase "sql server ilike it not" encapsulates this historical divergence: a reminder that SQL Server’s toolkit, while powerful, requires more manual intervention for tasks that other databases handle natively.
Core Mechanisms: How It Works
Under the hood, SQL Server’s case-insensitive matching relies on two primary mechanisms: collation and function-based transformations. Collation-based approaches (e.g., `COLLATE`) leverage the database’s internal rules for string comparison, which can be configured at the server, database, or column level. For example:```sql
CREATE TABLE Products (Name NVARCHAR(100) COLLATE SQL_Latin1_General_CP1_CI_AS);
```
Here, the `CI` (case-insensitive) flag ensures that `'Apple'` and `'apple'` are treated as identical during comparisons. However, this collation must be consistently applied across all relevant columns and queries, or results may vary unpredictably.
Table of Contents
- The Complete Overview of SQL Server’s Case-Insensitive Querying
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why doesn’t SQL Server have a native `ILIKE` like PostgreSQL?
- Q: How can I negate case-insensitive matching in SQL Server?
- Q: Does using `UPPER()`/`LOWER()` with `LIKE` affect performance?
- Q: Can I use `ILIKE` in Azure SQL Database?
- Q: What’s the best collation for case-insensitive searches in SQL Server?
- Q: Are there third-party tools to simplify `ILIKE` in SQL Server?
Function-based methods, such as `UPPER()` or `LOWER()`, convert strings to a uniform case before comparison:
```sql
WHERE UPPER(Name) LIKE '%APPLE%'
```
This approach is collation-agnostic but incurs performance costs, as it prevents the use of indexes on the original column. The trade-off between these methods often hinges on the query’s specific requirements—whether consistency or speed is prioritized.
Key Benefits and Crucial Impact
The absence of a native `ILIKE` in SQL Server isn’t just a technical limitation; it’s a catalyst for deeper architectural decisions. Developers who grapple with "sql server ilike it not" scenarios often discover that their queries become more explicit, forcing them to confront collation dependencies upfront. This clarity can reduce bugs in multilingual applications, where case-folding rules differ across languages. For instance, a German `ß` might not behave the same way as an English `'ss'` in case-insensitive comparisons, making collation awareness critical.Moreover, the need to simulate `ILIKE` behavior has spurred innovations in query optimization. Techniques like filtered indexes or persisted computed columns can mitigate the performance overhead of `UPPER()`/`LOWER()` by pre-processing data. These workarounds highlight how SQL Server’s constraints have indirectly driven advancements in database design.
> "SQL Server’s lack of ILIKE isn’t a flaw—it’s a feature that forces developers to design with collation in mind. The alternatives, while clunky, often lead to more robust systems." — Erin Stellato, SQL Server MVP
Major Advantages
- Collation Control: Explicit collation settings (e.g., `COLLATE`) allow fine-grained tuning of case sensitivity, accommodating regional language rules (e.g., Turkish dotted/I characters).
- Index Optimization: Using `COLLATE` on indexed columns preserves index usage, unlike `UPPER()`/`LOWER()`, which can bypass indexes.
- Legacy Compatibility: SQL Server’s collation model aligns with Windows’ locale settings, ensuring consistency in mixed environments (e.g., applications using Windows API calls).
- Performance Trade-offs: While `UPPER()`/`LOWER()` are slower, they offer flexibility in queries where collation isn’t uniformly applied.
- Future-Proofing: Workarounds like computed columns or dynamic SQL can adapt to future SQL Server versions without breaking existing logic.
Comparative Analysis
| SQL Server (Workaround) | PostgreSQL (Native ILIKE) |
|---|---|
|
|
|
|
|
|
Future Trends and Innovations
As SQL Server evolves, the demand for `ILIKE`-like functionality may push Microsoft to reconsider its stance. The rise of polyglot persistence—where applications use multiple databases—has already led to hybrid approaches, such as using PostgreSQL for case-insensitive features while keeping SQL Server for Windows-specific optimizations. Future versions of SQL Server could introduce a native `ILIKE` operator, especially if Microsoft prioritizes cross-platform compatibility in its cloud offerings (e.g., Azure SQL Database).Alternatively, developers may adopt query hinting or custom CLR functions to simulate `ILIKE` behavior more efficiently. Tools like Azure SQL Edge or SQL Server on Linux could also bridge the gap by adopting PostgreSQL-like features, though this remains speculative. For now, the "sql server ilike it not" dilemma persists as a reminder of how database design choices ripple across entire ecosystems.

Conclusion
The phrase "sql server ilike it not" is more than a colloquialism—it’s a symptom of SQL Server’s deliberate design philosophy, where flexibility comes at the cost of syntactic simplicity. While PostgreSQL’s `ILIKE` offers a streamlined solution, SQL Server’s collation-based approach provides granular control, albeit with added complexity. Developers must weigh the trade-offs: whether to embrace workarounds like `COLLATE` or `UPPER()`, or to push for broader adoption of case-insensitive features in future SQL Server iterations.Ultimately, understanding these nuances isn’t just about writing queries—it’s about designing systems that anticipate real-world variability. The next time you encounter "sql server ilike it not", remember: the challenge isn’t the tool, but how you wield it.
Comprehensive FAQs
Q: Why doesn’t SQL Server have a native `ILIKE` like PostgreSQL?
SQL Server’s design prioritizes collation integration with Windows’ locale settings, which allows for fine-grained control over case sensitivity. While PostgreSQL introduced `ILIKE` as a convenience, SQL Server’s approach ensures compatibility with legacy systems and regional language rules (e.g., Turkish case-folding). The trade-off is verbosity, but it offers flexibility in environments where collation must be explicitly managed.
Q: How can I negate case-insensitive matching in SQL Server?
SQL Server lacks a native `NOT ILIKE`, but you can simulate it using:
```sql
WHERE column NOT LIKE '%pattern%' COLLATE SQL_Latin1_General_CP1_CI_AS
```
or
```sql
WHERE UPPER(column) NOT LIKE '%PATTERN%'
```
Note that the first method respects collation, while the second bypasses indexes.
Q: Does using `UPPER()`/`LOWER()` with `LIKE` affect performance?
Yes. Functions like `UPPER()` prevent index usage on the original column, forcing SQL Server to perform a full table scan. For large tables, this can degrade performance significantly. Collation-based approaches (`COLLATE`) are more efficient if the column is indexed with the same collation.
Q: Can I use `ILIKE` in Azure SQL Database?
No, Azure SQL Database inherits SQL Server’s syntax limitations. However, you can use the same workarounds (`COLLATE`, `UPPER()`/`LOWER()`). If case-insensitive matching is critical, consider using PostgreSQL-compatible features via Azure Database for PostgreSQL or implementing application-layer logic.
Q: What’s the best collation for case-insensitive searches in SQL Server?
The default `SQL_Latin1_General_CP1_CI_AS` works for most English-based applications, but for multilingual support, consider:
Q: Are there third-party tools to simplify `ILIKE` in SQL Server?
Some ORMs (e.g., Entity Framework) or query builders (e.g., Dapper) abstract away collation details, but they still rely on SQL Server’s underlying mechanics. For direct SQL, tools like SQL Prompt (Redgate) or ApexSQL can help manage collation settings, but no tool replaces the need to understand the syntax.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Viralcontentbee.