How Python’s `append()` Transforms Lists—Mastering Dynamic Data Manipulation
Python’s ability to dynamically modify lists at runtime is a cornerstone of its flexibility. The `append()` method—often invoked as `python append to list`—serves as the linchpin for expanding collections without manual reallocation. Unlike languages where arrays require preallocation, Python’s lists grow organically, absorbing new elements with minimal overhead. This fluidity underpins everything from data pipelines to real-time analytics, where lists evolve as programs execute.
Yet, the simplicity of `append()` belies its complexity. Under the hood, Python’s memory management and list resizing strategies ensure amortized O(1) performance, though edge cases like frequent appends can trigger costly reallocations. Developers often overlook these nuances, leading to inefficiencies in high-performance applications. Understanding how `append()` interacts with Python’s memory model is critical for writing scalable code.
The method’s ubiquity extends beyond basic usage. From building queues to implementing custom data structures, `python append to list` operations form the backbone of algorithmic solutions. Whether you’re processing logs, managing configurations, or simulating dynamic systems, mastering this operation unlocks cleaner, more maintainable code.
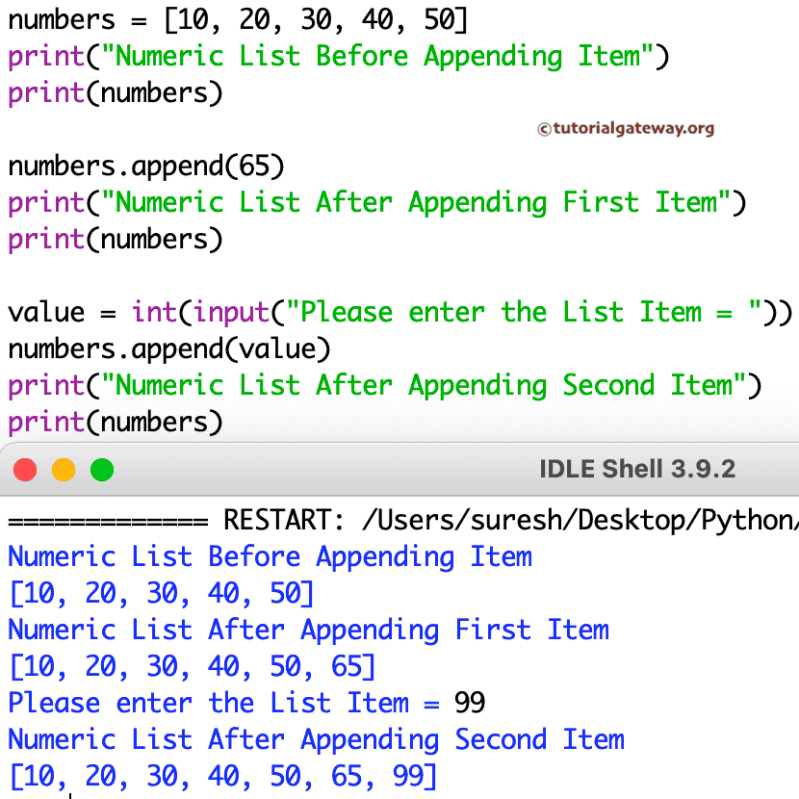
The Complete Overview of Python Append to List
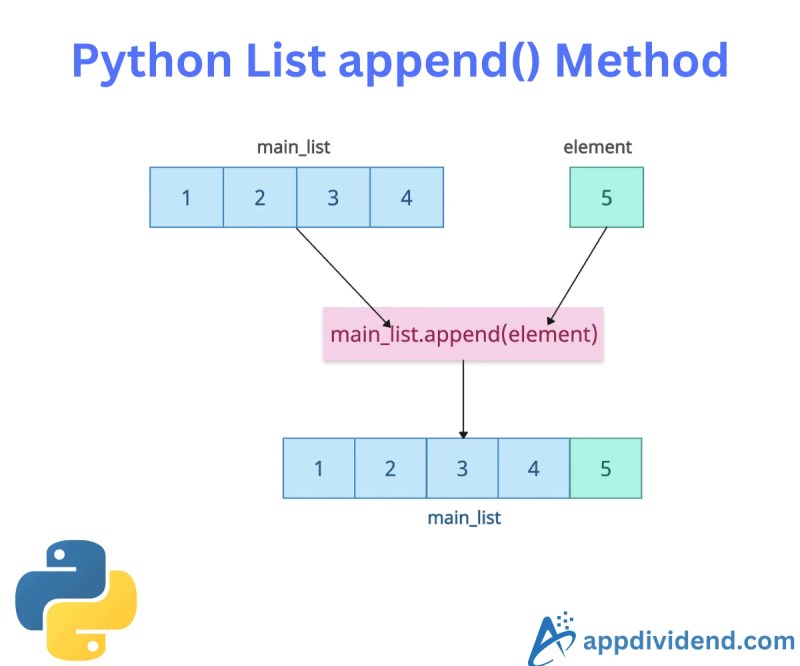
Python’s `append()` method is a fundamental tool for extending lists, but its implementation reflects deeper design choices. Unlike immutable sequences (e.g., tuples), lists in Python are mutable, allowing in-place modifications. When you call `list.append(x)`, Python doesn’t create a new list—instead, it modifies the existing object by adding `x` to the end. This behavior aligns with Python’s philosophy of efficiency and readability, where operations like `python append to list` are both intuitive and performant for most use cases.The method’s simplicity masks its reliance on low-level optimizations. Python’s list objects are implemented as dynamic arrays, which resize automatically when capacity is exceeded. This resizing follows an exponential growth pattern (typically doubling capacity), ensuring that appends remain efficient over time. However, this strategy introduces a trade-off: while individual appends are O(1), prolonged sequences may incur occasional O(n) resizing costs. Recognizing this trade-off helps developers anticipate performance bottlenecks in resource-constrained environments.
Historical Background and Evolution
The `append()` method emerged as part of Python’s core data structures in the language’s early days, reflecting Guido van Rossum’s emphasis on simplicity and practicality. Before Python 2.0, list operations were less optimized, and manual resizing was common. The introduction of dynamic arrays in Python 2.0 standardized `append()` as a built-in method, aligning with the growing need for efficient sequential data handling.Over time, Python’s memory management evolved to handle `append()` more intelligently. Modern implementations (e.g., CPython) use preallocation heuristics to minimize resizing overhead. For instance, lists now allocate extra memory during resizing to reduce future reallocations—a technique borrowed from languages like Java’s `ArrayList`. This evolution underscores how `python append to list` operations have become a benchmark for Python’s performance improvements, balancing speed with memory efficiency.
Core Mechanisms: How It Works
At its core, `append()` modifies a list’s internal array by:1. Checking capacity: If the list is full, Python allocates a new array (typically 1.125× larger) and copies existing elements.
2. Inserting the element: The new item is placed at the end, and the list’s `len` attribute is incremented.
3. Updating references: All external references to the list remain valid, as the object’s identity persists.
Table of Contents
- The Complete Overview of Python Append to List
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does `append()` differ from `+=` for lists?
- Q: Can I use `append()` with immutable objects (e.g., tuples)?
- Q: What happens if I `append()` to a list while iterating over it?
- Q: Are there performance pitfalls with frequent `append()` calls?
- Q: How does `append()` handle non-hashable types (e.g., lists or dicts)?
- Q: What’s the fastest way to append multiple elements to a list?
This process ensures that `python append to list` operations are amortized O(1), meaning the average time per append approaches constant complexity. However, the occasional resize operation can introduce latency spikes, particularly in loops where many appends occur. For example:
```python
data = []
for i in range(1_000_000):
data.append(i) # Mostly O(1), but ~20 resizes occur
```
Understanding this mechanism is key to optimizing bulk operations, where preallocating lists (e.g., `data = [None] 1_000_000`) can eliminate resizing entirely.
Key Benefits and Crucial Impact
The `append()` method’s design addresses a fundamental need in programming: dynamic data expansion without manual memory management. By abstracting away resizing logic, Python empowers developers to focus on algorithmic logic rather than low-level optimizations. This abstraction is particularly valuable in data-intensive applications, where lists frequently grow or shrink based on runtime conditions.Beyond convenience, `append()` enables idiomatic Python patterns. For instance, it’s the preferred way to build collections in loops, as seen in:
```python
results = []
for item in generator:
results.append(item) # Cleaner than alternatives like += or extend()
```
This clarity reduces cognitive load, making code easier to debug and maintain.
"The beauty of Python’s append is that it hides complexity while delivering performance. It’s the kind of feature that makes the language feel both powerful and approachable." — Guido van Rossum (Python Creator, 2021)
Major Advantages
- Amortized O(1) performance: Most appends are fast, with occasional resizing costs distributed evenly.
- Memory efficiency: Exponential resizing minimizes wasted space, unlike fixed-size arrays.
- Thread safety (for single operations): `append()` is atomic, making it safe in single-threaded contexts (though not for concurrent modifications).
- Compatibility with iterables: Works seamlessly with generators, iterators, and other sequences.
- Readability: Explicit and intuitive syntax (`list.append(x)`) reduces ambiguity in code reviews.
Comparative Analysis
| Feature | Python `append()` | Alternative Methods |
|---|---|---|
| Performance | O(1) amortized; occasional O(n) resizes | `+=` (O(n) per operation), `extend()` (O(k) for k elements) |
| Use Case | Adding single elements dynamically | `extend()` for iterables, `+=` for scalars/lists |
| Memory Overhead | Low (exponential resizing) | High (e.g., `+=` creates new lists) |
| Thread Safety | Safe for single operations | Unsafe for concurrent modifications |
Future Trends and Innovations
As Python evolves, so too will optimizations for `append()`-like operations. Projects like PEP 703 (memory management improvements) and CPython’s slot classes aim to reduce memory overhead for large lists, potentially making resizing even more efficient. Additionally, the rise of just-in-time (JIT) compilation (e.g., via PyPy) could further accelerate append-heavy workloads by optimizing hot loops.For developers, the future lies in hybrid approaches. Combining `append()` with preallocation (e.g., `list.__init__(self, iterable)`) or using specialized libraries (e.g., `numpy.append()` for numerical data) will become more common. As Python’s ecosystem matures, understanding these nuances will distinguish efficient code from naive implementations.

Conclusion
The `append()` method is more than a syntactic convenience—it’s a testament to Python’s balance of simplicity and performance. By abstracting away memory management, it allows developers to focus on solving problems rather than managing infrastructure. Whether you’re processing streams of data, building dynamic configurations, or prototyping algorithms, `python append to list` remains a reliable tool.However, its power comes with responsibility. Ignoring resizing costs in performance-critical code can lead to inefficiencies, while over-optimizing may sacrifice readability. The key is awareness: knowing when to use `append()`, when to preallocate, and when to consider alternatives like `collections.deque` for append-heavy workloads.
Comprehensive FAQs
Q: How does `append()` differ from `+=` for lists?
`append()` adds a single element to the end of a list (O(1) amortized), while `+=` (e.g., `list += [x]`) creates a new list and copies all elements (O(n)). For single items, `append()` is always faster and more memory-efficient.
Q: Can I use `append()` with immutable objects (e.g., tuples)?
Yes, but the object itself isn’t modified—only the list’s reference to it changes. For example, `data.append((1, 2))` adds a tuple to the list without altering the tuple’s contents.
Q: What happens if I `append()` to a list while iterating over it?
This is unsafe in Python. Iterating and modifying a list simultaneously can lead to skipped elements or `RuntimeError`. Use a copy (e.g., `for item in data[:]`) or a loop index if modifications are needed.
Q: Are there performance pitfalls with frequent `append()` calls?
Yes. While individual appends are O(1), repeated calls can trigger multiple resizes, increasing latency. Preallocating lists (e.g., `data = [None] size`) or using `deque` for append-heavy workloads can mitigate this.
Q: How does `append()` handle non-hashable types (e.g., lists or dicts)?
`append()` works with any object, including mutable types. However, using mutable objects as list elements can lead to unintended side effects if references are shared. For example, `data.append([])` adds a new list, but modifying it later affects all references to that object.
Q: What’s the fastest way to append multiple elements to a list?
For bulk operations, `extend(iterable)` or `list += iterable` is faster than looping with `append()`. For numerical data, `numpy.append()` or `numpy.concatenate()` offers further optimizations.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Viralcontentbee.