sql unique Constraints: Mastering Data Integrity in Modern Databases
The sql unique constraint is a cornerstone of relational database design, ensuring no duplicate values exist in specified columns. Unlike primary keys, which enforce uniqueness and non-nullability, a sql unique constraint allows nulls—making it indispensable for scenarios like email validation or user identification. Its precision in maintaining data consistency distinguishes it from other integrity mechanisms, yet its subtleties often lead to misconfigurations or performance bottlenecks.
Developers frequently underestimate the ripple effects of improperly implemented sql unique rules. A poorly indexed unique constraint can transform a high-performance query into a resource drain, while overlooked null handling may violate business logic. The distinction between `UNIQUE` and `PRIMARY KEY` is critical: the former permits nulls (with at most one null per column), while the latter rejects them entirely. This nuance becomes pivotal in multi-column constraints or partitioned tables.
The sql unique constraint’s role extends beyond basic validation. It underpins referential integrity in foreign keys, optimizes join operations, and enables efficient indexing strategies. However, its effectiveness hinges on proper syntax, indexing, and understanding edge cases—such as composite uniqueness or case-sensitive comparisons. Below, we dissect its mechanics, benefits, and comparative advantages in modern database architectures.
The Complete Overview of sql unique Constraints
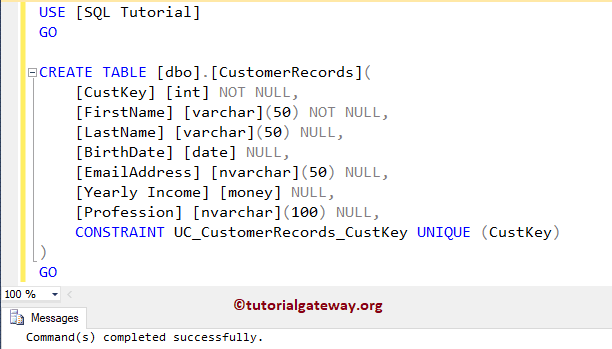
A sql unique constraint is a declarative rule that enforces uniqueness across one or more columns in a table. While primary keys inherently enforce uniqueness, sql unique constraints provide flexibility by allowing null values (with the caveat that only one null is permitted per column). This makes them ideal for scenarios where uniqueness is required but nulls are semantically valid—for example, tracking user emails where some records might lack an email address.The syntax for defining a sql unique constraint varies slightly by database system (e.g., PostgreSQL, MySQL, SQL Server), but the core principle remains consistent. In PostgreSQL, for instance, you might use:
```sql
ALTER TABLE users ADD CONSTRAINT unique_email UNIQUE (email);
```
This ensures no two rows share the same non-null `email` value. The constraint is automatically indexed, improving query performance for equality checks. However, the absence of an explicit index can degrade performance in high-write environments, necessitating manual index creation in some cases.
Historical Background and Evolution
The concept of sql unique constraints emerged alongside relational database theory in the 1970s, formalized by Edgar F. Codd’s rules for relational integrity. Early database systems like IBM’s System R (1974) introduced basic uniqueness guarantees, but the modern sql unique syntax standardized in SQL-92. This evolution reflected growing complexity in data models, where composite keys and multi-column uniqueness became essential for accurate representations of real-world entities.Database vendors later refined sql unique implementations to address performance and scalability challenges. For example, Oracle’s `UNIQUE` constraints now support invisible indexes, allowing administrators to defer indexing until necessary. Meanwhile, PostgreSQL’s `PARTIAL UNIQUE` (via `EXCLUDE` constraints) extends uniqueness to conditional logic, enabling advanced use cases like enforcing uniqueness within a date range.
Core Mechanisms: How It Works
At the engine level, a sql unique constraint triggers when an `INSERT` or `UPDATE` operation attempts to duplicate a non-null value in a constrained column. The database first checks the constraint’s index (if one exists) and rejects the operation if a duplicate is found. For composite sql unique constraints (e.g., `UNIQUE (column1, column2)`), the combination of values must be unique, not individual columns.Table of Contents
- The Complete Overview of sql unique Constraints
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can a sql unique constraint be added to an existing table with duplicates?
- Q: How does a composite sql unique constraint differ from a primary key?
- Q: Does every sql unique constraint require an index?
- Q: Can sql unique constraints improve query performance?
- Q: What happens if a sql unique constraint violation occurs in a transaction?
Performance hinges on indexing: most databases auto-create a B-tree index for sql unique constraints, but this behavior can be overridden. In MySQL, for example, `UNIQUE` constraints on `TEXT` or `BLOB` columns may require explicit indexing due to size limitations. Additionally, sql unique constraints interact with transactions—violations roll back the entire transaction unless configured otherwise.
Key Benefits and Crucial Impact
The sql unique constraint is more than a technical feature; it’s a safeguard against data corruption and a catalyst for efficient querying. By preventing duplicates, it ensures referential integrity in foreign key relationships, reducing anomalies in multi-table schemas. For instance, a sql unique constraint on a `user_id` in a `orders` table guarantees each order is linked to exactly one user, simplifying audits and analytics.Beyond integrity, sql unique constraints optimize query execution. Databases leverage their associated indexes to accelerate `WHERE`, `JOIN`, and `GROUP BY` operations, often eliminating full-table scans. This dual role—enforcing rules while improving performance—makes sql unique a foundational tool in database design.
> "A sql unique constraint is the digital equivalent of a serial number: it doesn’t just prevent duplicates; it transforms raw data into a structured, trustworthy asset." — Martin Fowler, Database Refactoring
Major Advantages
- Data Integrity: Eliminates duplicate records, preserving accuracy in critical systems (e.g., financial transactions).
- Indexing Efficiency: Auto-generated indexes speed up equality-based queries without manual intervention.
- Flexibility: Supports composite keys and partial uniqueness (e.g., `UNIQUE (department_id, employee_id)`).
- Transaction Safety: Violations trigger rollbacks, preventing partial updates that could corrupt data.
- Schema Clarity: Explicit constraints document business rules, aiding collaboration among developers and analysts.

Comparative Analysis
| Feature | sql unique Constraint | Primary Key |
|---|---|---|
| Null Values | Permits one null per column | Rejects all nulls |
| Indexing | Auto-indexed (configurable) | Always indexed |
| Composite Support | Yes (multi-column) | Yes (multi-column) |
| Use Case | Non-identifying uniqueness (e.g., emails) | Row identification (e.g., `id` columns) |
Future Trends and Innovations
The future of sql unique constraints lies in hybrid approaches that blend declarative rules with procedural logic. PostgreSQL’s `EXCLUDE` constraints, for example, enable partial uniqueness (e.g., "no two users in the same department can have the same salary"). As databases evolve, we’ll see broader adoption of sql unique variants that support:Cloud-native databases are also redefining sql unique constraints through dynamic indexing and auto-scaling, reducing manual tuning requirements.

Conclusion
The sql unique constraint remains a linchpin of relational database design, balancing flexibility with rigor. Its ability to enforce uniqueness without mandating non-nullability makes it indispensable for modern applications, from e-commerce platforms to scientific data repositories. However, its effectiveness depends on thoughtful implementation—proper indexing, composite key design, and awareness of null handling.As databases grow in complexity, sql unique constraints will continue to adapt, integrating with new paradigms like temporal data and distributed systems. Developers who master these constraints today will be best positioned to leverage tomorrow’s innovations.
Comprehensive FAQs
Q: Can a sql unique constraint be added to an existing table with duplicates?
A: No. A sql unique constraint cannot be enforced on a table containing duplicate values without first resolving the duplicates via `DELETE` or `UPDATE`. Attempting to add the constraint will fail with an error.
Q: How does a composite sql unique constraint differ from a primary key?
A: A composite sql unique constraint enforces uniqueness across multiple columns but allows nulls (with one null per column), whereas a composite primary key rejects all nulls and serves as the table’s identifier. For example, `UNIQUE (first_name, last_name)` permits one null `first_name` but no duplicate `(John, Doe)` pairs.
Q: Does every sql unique constraint require an index?
A: Most databases auto-create an index for sql unique constraints, but this behavior can be overridden. In MySQL, for instance, `UNIQUE` constraints on large columns (e.g., `TEXT`) may need explicit indexing due to storage limits.
Q: Can sql unique constraints improve query performance?
A: Yes. The indexes associated with sql unique constraints accelerate equality-based queries (e.g., `WHERE email = 'user@example.com'`), often replacing full-table scans with index seeks. However, overuse can bloat the index structure.
Q: What happens if a sql unique constraint violation occurs in a transaction?
A: The entire transaction rolls back, and the operation fails. To handle this programmatically, wrap the operation in a `TRY-CATCH` block (SQL Server) or `EXCEPTION` handler (PostgreSQL) and implement retry logic.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Viralcontentbee.